
Fault Tolerance in AI Pipelines: Step-by-Step Guide
Fail closed on bad data, retry only safe errors, and make every pipeline step restartable to prevent outages and costly retries.
Updates, guides, and insights
Showing
168 posts found for 'models'
Fail closed on bad data, retry only safe errors, and make every pipeline step restartable to prevent outages and costly retries.
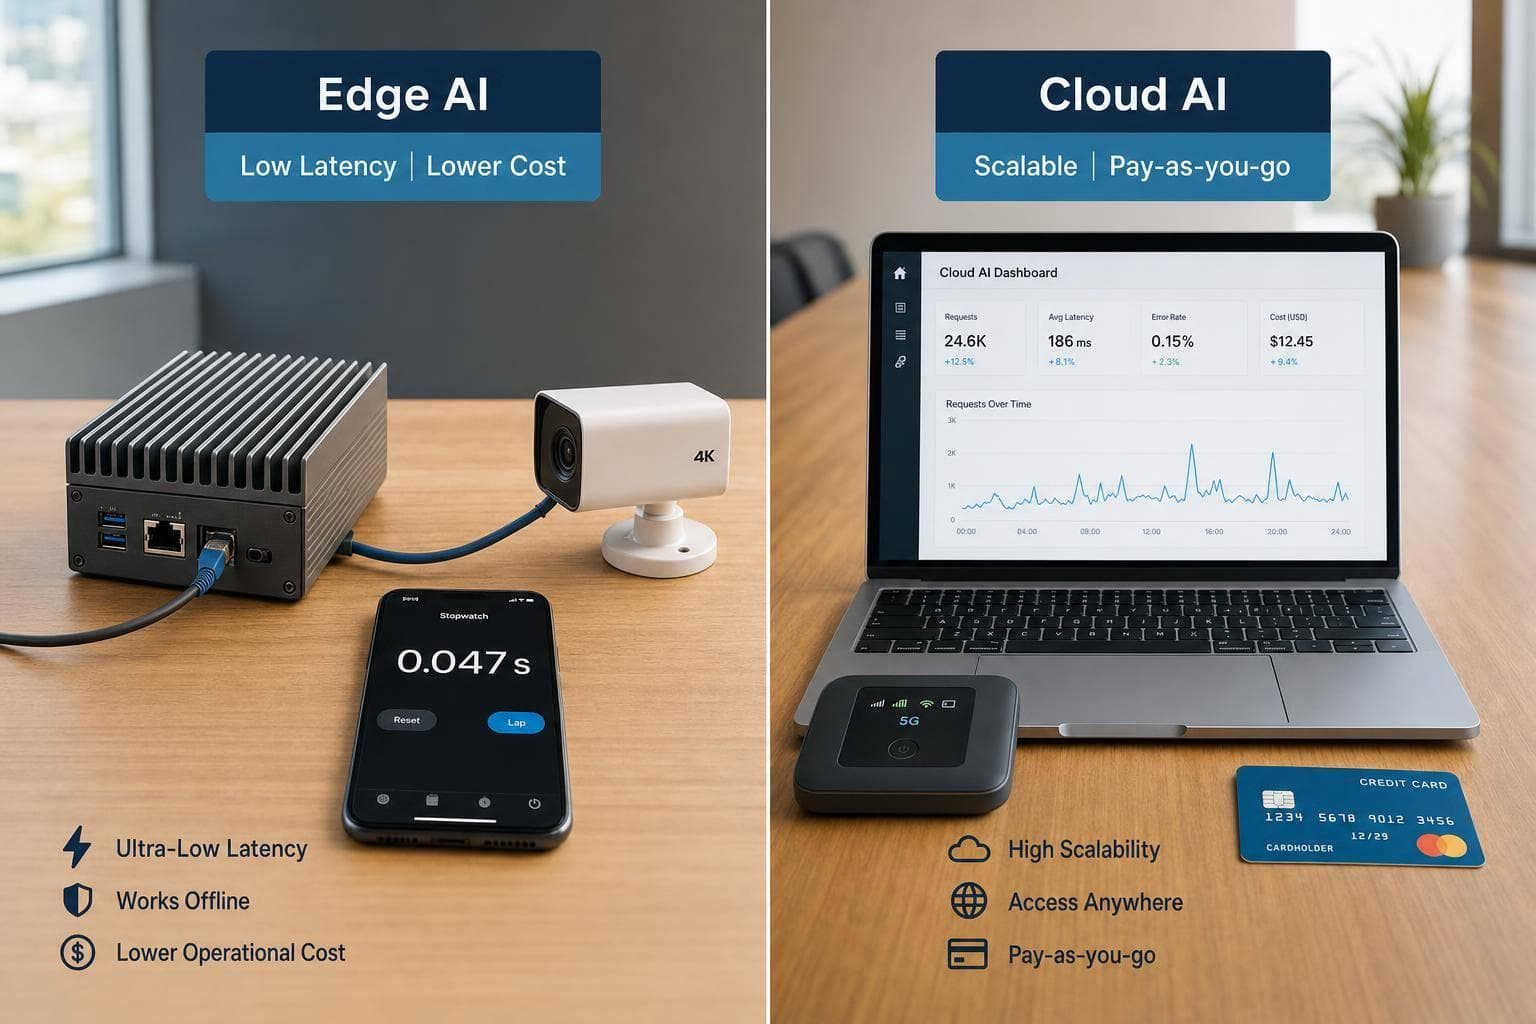
Edge offers sub-50 ms latency and lower bandwidth at higher upfront cost; cloud gives pay-as-you-go scaling for light, bursty workloads.
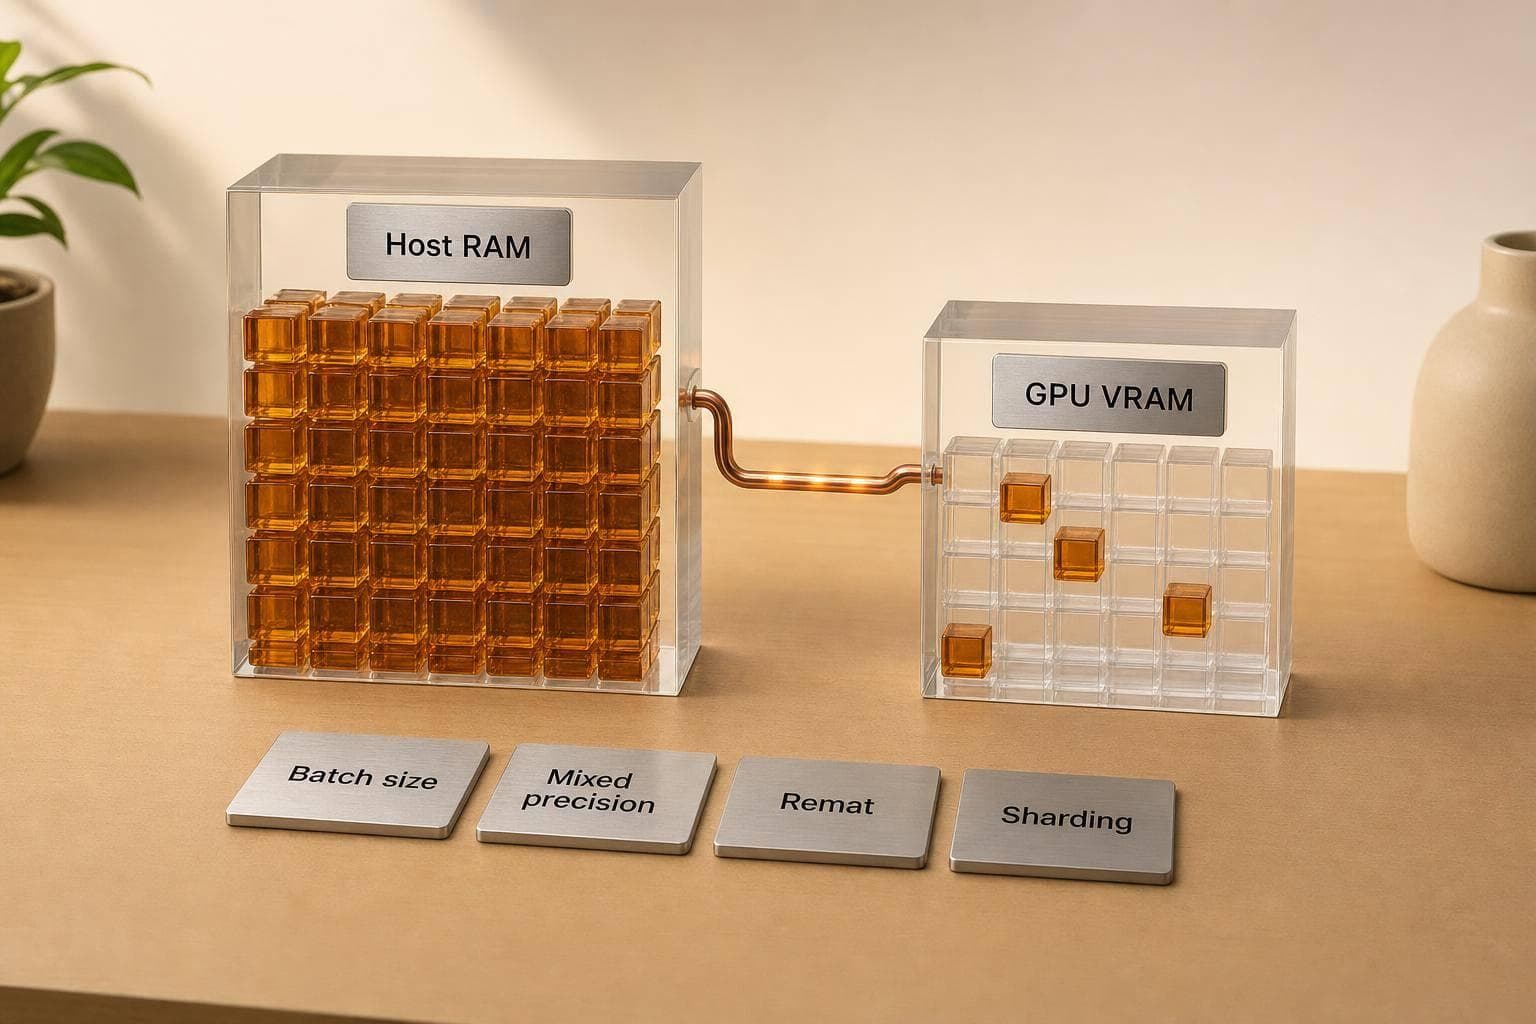
Explains why JAX reserves GPU memory, how to diagnose host vs device OOM, and fixes: batch size, mixed precision, remat, sharding.
Protect uptime first: use small models, caching, batch/live separation, tool offload, metrics-based routing and failover.
Adapting labeled models to unlabeled target data fixes domain shift using alignment, adversarial training, and pseudo-labels.
Compress ONNX models to cut size and latency with quantization, pruning, and mixed-precision—practical tools and deployment tips.
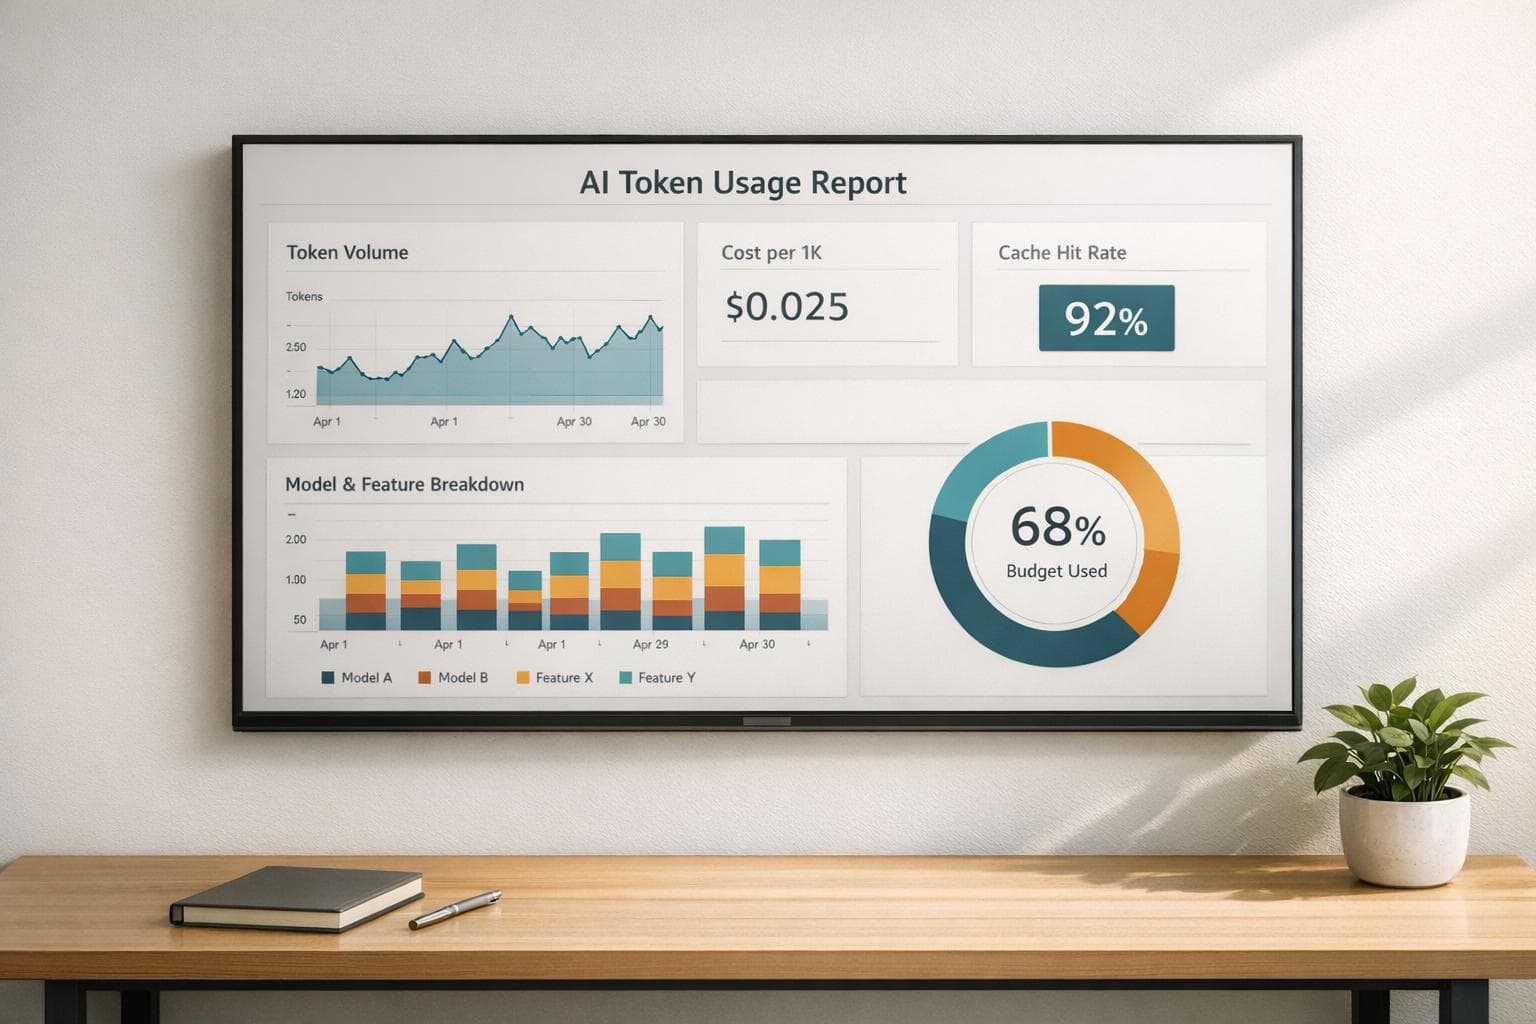
Build clear AI token usage reports with token volume, cost per 1K, model/feature breakdowns, cache hit rates, and budgeting.
Run AI models locally for privacy, lower latency, and cloud-free performance — hardware, quantization, GGUF formats, and tools.
Compare local, cloud, and enterprise AI retention options, risks, and best practices for regulatory compliance.
Compare the top five containerization tools for GPU-accelerated AI, covering GPU support, scalability, integrations, and security.